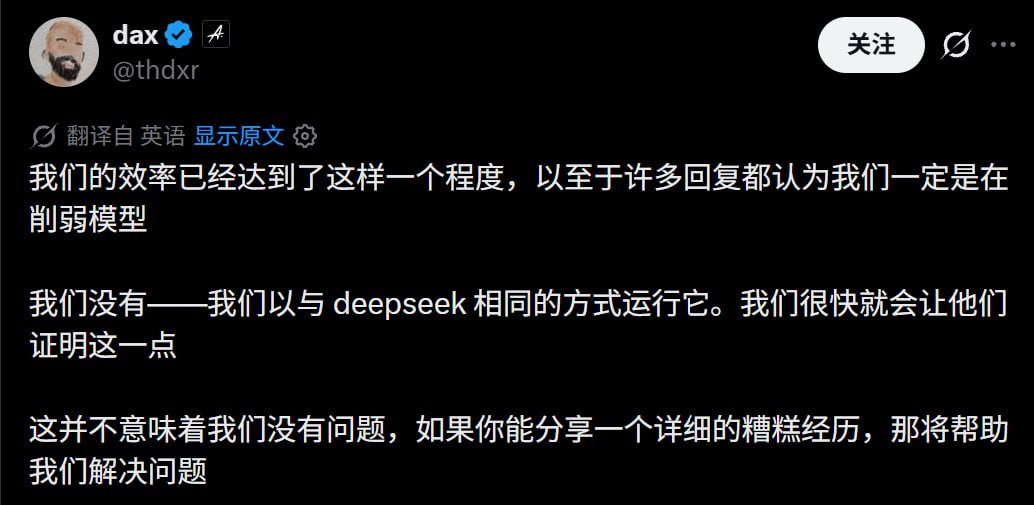
OpenCode Staff Deny Quantization Weakened DeepSeek V4.1 Flash Model, Claiming Official Proof Coming Soon
OpenCode developer Dax has refuted community claims that the platform has quietly downgraded the DeepSeek V4.1 Flash model through quantization. He stated that the platform operates identically to DeepSeek's official version and will be officially certified. He explained that the Flash expert layer is natively in FP4 quantization, making secondary quantization pointless, and invited users to report any specific issues.
OpenCode staff deny quantization weakened the DeepSeek V4.1 Flash model, stating the official team will soon prove it
In response to recent community suspicions that OpenCode had quietly weakened the DeepSeek V4.1 Flash model through quantization, its developer Dax posted a clarification. He stated that the platform operates in a manner completely consistent with the official DeepSeek implementation and that the official team will soon provide verification. He also noted that DeepSeek Flash's expert layers are natively FP4-quantized, making any secondary quantization pointless. At the same time, he welcomed users to share specific negative experiences to help the team address the issues.