NVIDIA Optimizes Kimi K3 Inference Speed
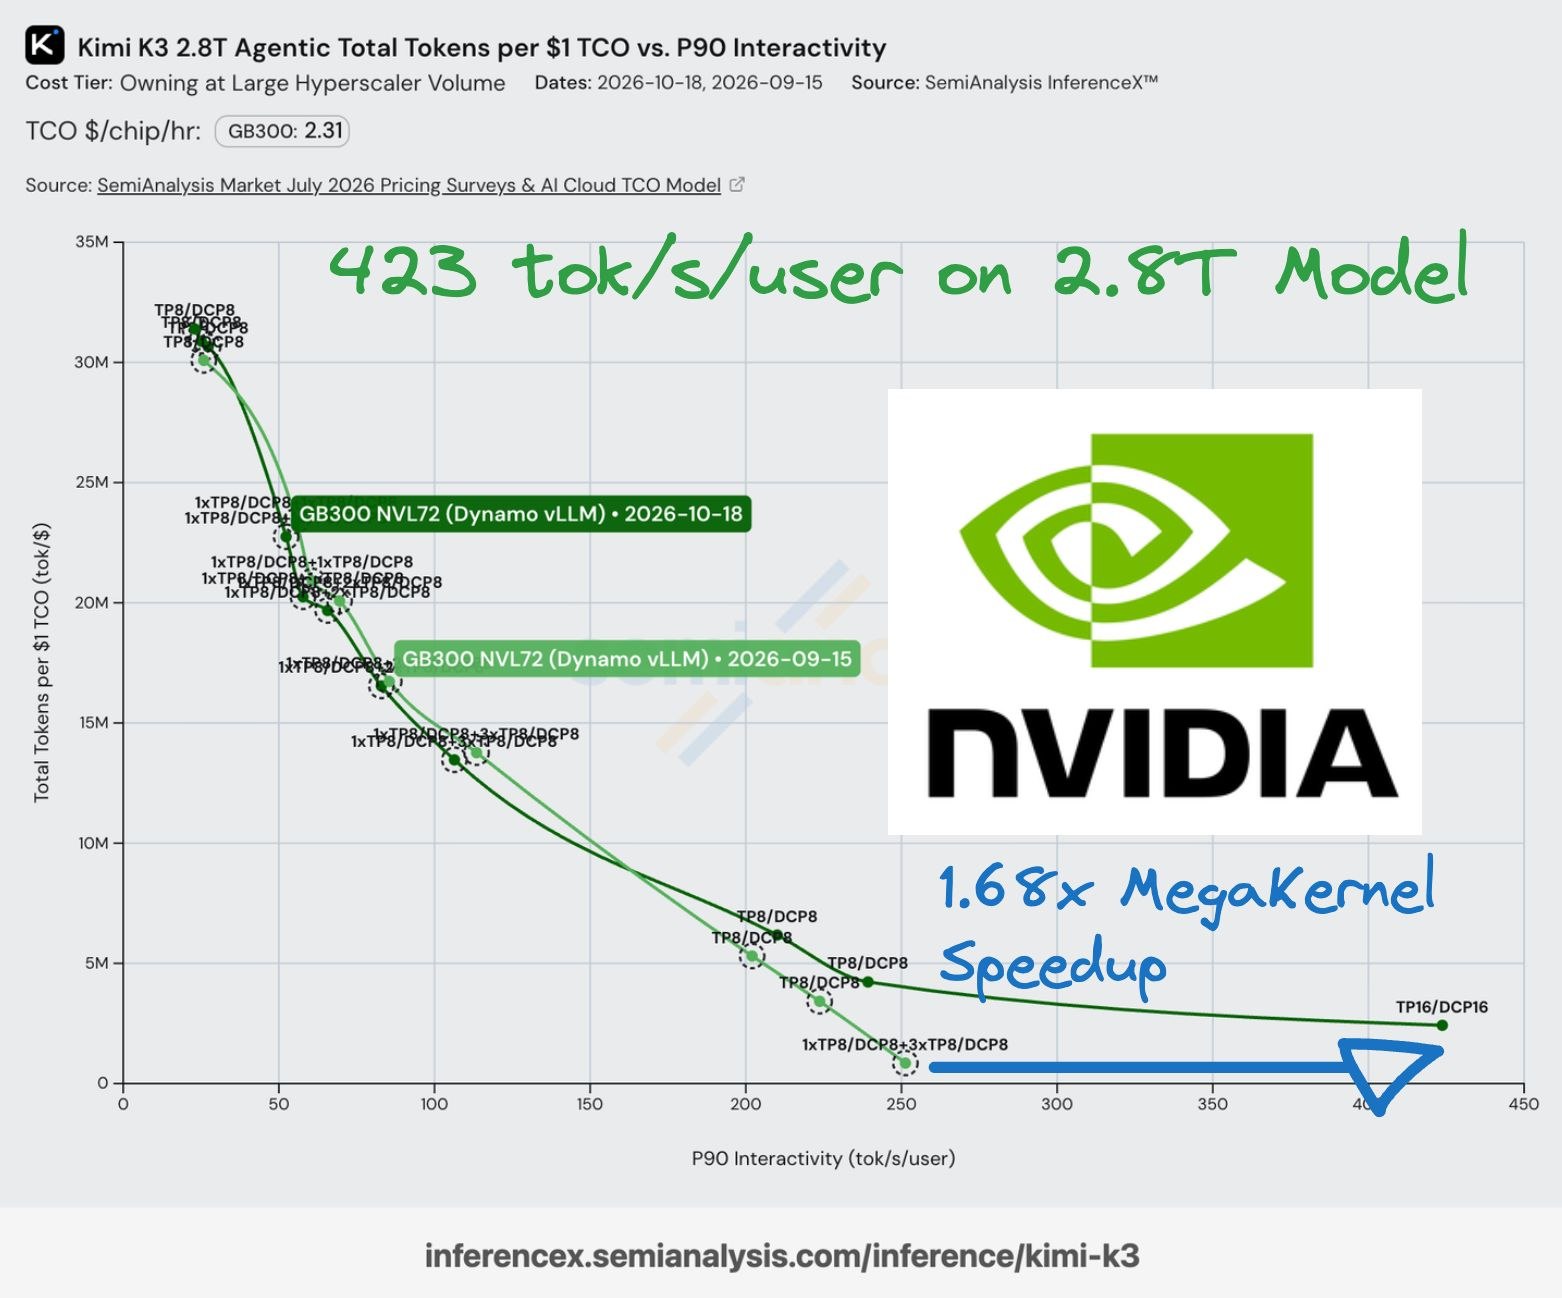
SemiAnalysis reports that NVIDIA, through upstream vLLM optimizations, achieved 423 tokens per user per second on the 2.8-trillion-parameter Kimi K3, a 1.68x speedup on the same hardware. CentML's Benjamin wrote a decoding-specific kernel using Cute DSL and optimized it via Megakernel fusion. NVIDIA is also adapting vLLM for models like DeepSeek v4.1.
On this page
NVIDIA Optimizes Kimi K3 Inference Speed
SemiAnalysis reported that, through an upstream vLLM optimization, NVIDIA achieved a speed of 423 tokens per second per user on the 2.8-trillion-parameter Kimi K3 model—a 1.68x improvement on the same hardware.
The post states that Benjamin from NVIDIA's CentML wrote a decoding-specific kernel using Cute DSL and optimized it by fusing it into a Megakernel. NVIDIA is also working on adapting vLLM for models such as DeepSeek v4.1.
SemiAnalysis(@SemiAnalysis_)
https://x.com/SemiAnalysis_/status/2111627094878790023