AI "Tokenizer Taxes" Can Make Some Languages Up to 17 Times More Expensive to Use
The CLEAR research consortium reports that tokenizers in mainstream AI models are biased toward English and high-resource languages. The same content consumes more tokens in some non-English languages, with disparities reaching up to 17x, which drives up costs, increases latency, and reduces context capacity.
AI "Tokenizer Tax" Can Make Language Costs Up to 17 Times Higher
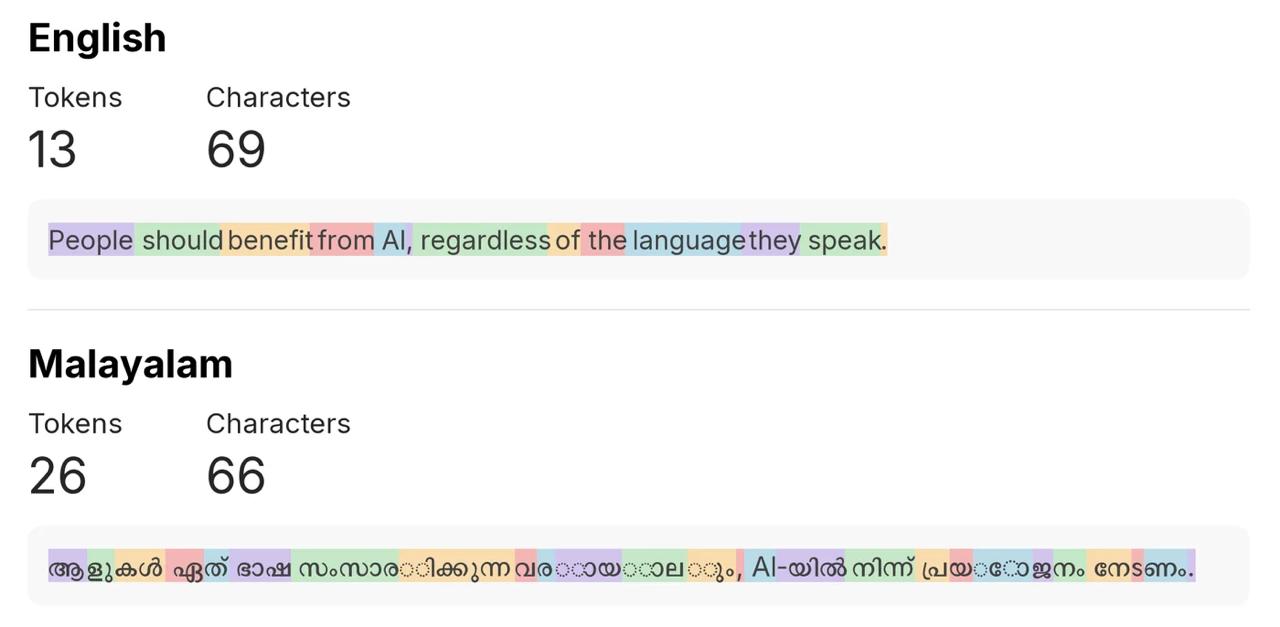
A report by the CLEAR research consortium points out that tokenizers in mainstream AI models are significantly optimized for English and high-resource languages. This causes some non-English languages to consume more tokens when processing the same content. For example, the same sentence requires 13 tokens in English, 26 in Malayalam, and as many as 78 in Amharic. The study, which covered approximately 200 languages, found that the difference in token consumption between languages can be as high as 17 times. This not only increases costs for users but also leads to higher response latency and reduces the effective context capacity.
Rest of World | Clear
https://clear-languages.org/blog/the-tokenizer-tax